Catching SEO Regressions After a Deploy: The Checks Worth Re-Running
Catch SEO regressions after a deploy: baseline production, then re-check robots.txt, noindex, canonicals, redirects, raw HTML and certificates on every release.
To catch SEO regressions after a deploy, record what production serves before you ship, then re-check the same things on the live site within minutes of the release: robots.txt, the robots meta tag and X-Robots-Tag header, canonical tags, redirects on any changed route, the raw HTML a crawler receives, and the TLS certificate. Compare each answer with the baseline, not with what you think the site does. Then re-run the comparison on a schedule, because the regressions that hurt most are the ones nobody deployed on purpose. This applies to any small team shipping weekly or faster to a site it owns, with no SEO person reviewing each release.
This guide covers:
the six regressions that realistically reach production on a small team, and how soon each one shows
a numbered post-deploy procedure, one check per step, with the usual failure at each step and how to recover
a worked example of one weekly release carried through every step
a copyable checklist template
what a single post-deploy check cannot see, and how to cover the gap
Why traffic graphs catch regressions too late
Most advice on this problem starts with a traffic drop and works backwards. That is diagnosis after the damage: by the time a traffic graph bends, a crawler has already fetched the broken page, processed it, and acted on it. The reason is simple. Search engines and answer engines read your production site on their own schedule, so the gap between your deploy and their next visit is the only window in which a regression costs you nothing.
Newsletter
What launched, every Monday
Every Monday: what launched on LaunchScaler that week, what is launching next, and the reviews we published. Confirm your email once and you're in.
The checks in this guide are all things you can see yourself, on the live site, before any crawler reports them. None of them needs a paid tool. They need a baseline, a terminal or a browser, and the discipline to run them every release rather than only when something already looks wrong.
The six regressions that actually reach production
These are the failures a small team shipping weekly hits in practice. Each one passes code review easily, because the change that causes it usually looks unrelated to search.
Regression
Typical cause
How it shows up
How soon it matters
Earliest place you can see it
Staging noindex reaches production
An environment variable or build flag meant for staging ships to production
Pages drop out of the index one by one as they are recrawled
On the next crawl of each page
View source or response headers on production
robots.txt overwritten
A framework default, a new static file, or a staging robots.txt copied in the build
Crawlers stop fetching blocked paths; new pages never get crawled
On the next robots.txt fetch
The served robots.txt file, opened in a browser
Canonical points at the wrong host
A base URL setting left as a staging, preview or plain HTTP host
Search engines treat another host as the original; your pages are dropped as duplicates
As pages are recrawled and reprocessed
The <link rel="canonical"> in production HTML
Redirect chain after a route change
A renamed route redirects to an old redirect, or trailing slash rules stack on top of it
Slower discovery, lost link value, sometimes a loop that returns nothing
Immediately for visitors; on recrawl for search
Following the old URL hop by hop
Content moved behind client-side rendering
A page rebuilt as a client component, or data fetched only in the browser
The raw HTML holds a shell; crawlers that do not run JavaScript, and many AI fetchers, see an empty page
On the next fetch by a non-rendering client
Comparing raw HTML with the rendered page
Expired or mismatched certificate
Auto-renewal failed, a new subdomain or CDN without a certificate
Browsers show a warning; crawlers may fail to fetch
The moment the certificate lapses
Certificate details in the browser or via openssl
Two of these are not deploy regressions in the strict sense. A certificate expires on a date, not on a release, and a robots.txt can be overwritten by a hosting platform change you never pushed. They belong on the list because the symptom is identical: something that worked last week no longer works, and nothing in your own change log explains it.
If you are fixing a site that has never been indexed at all, rather than one that regressed, the order of causes is different; why your new site isn't showing up on Google walks through that case.
How do you catch SEO regressions after a deploy, step by step?
Run these in order. The first step happens before you ship; the rest happen against production, not against staging or a preview URL, because the whole point is to see what a crawler sees.
Save a baseline of production before the release. For a short list of representative URLs (the home page, one page per template, the pricing page, and any URL the release touches), save the response status, the response headers, the raw HTML, the canonical URL, the robots meta value and the current robots.txt. A folder of text files from curl -s and curl -sI is enough. Where it fails: teams baseline staging instead of production, so the comparison hides exactly the difference they need to see. Recovery: if you have no baseline, use the last known good build or a cached copy, and start saving one from this release on.
Fetch robots.txt from production and diff it against the baseline. Open the /robots.txt path on your production host directly. Look for a Disallow: / under User-agent: *, new disallowed paths that cover real content, and a missing or changed Sitemap: line. Check the response status too: a robots.txt that returns an error page is not the same as one that returns your rules. Where it fails: the file in the repository is correct, but the platform or CDN serves a different one. Recovery: always test the served file, and if it differs from the repository, find which layer is generating it before editing anything.
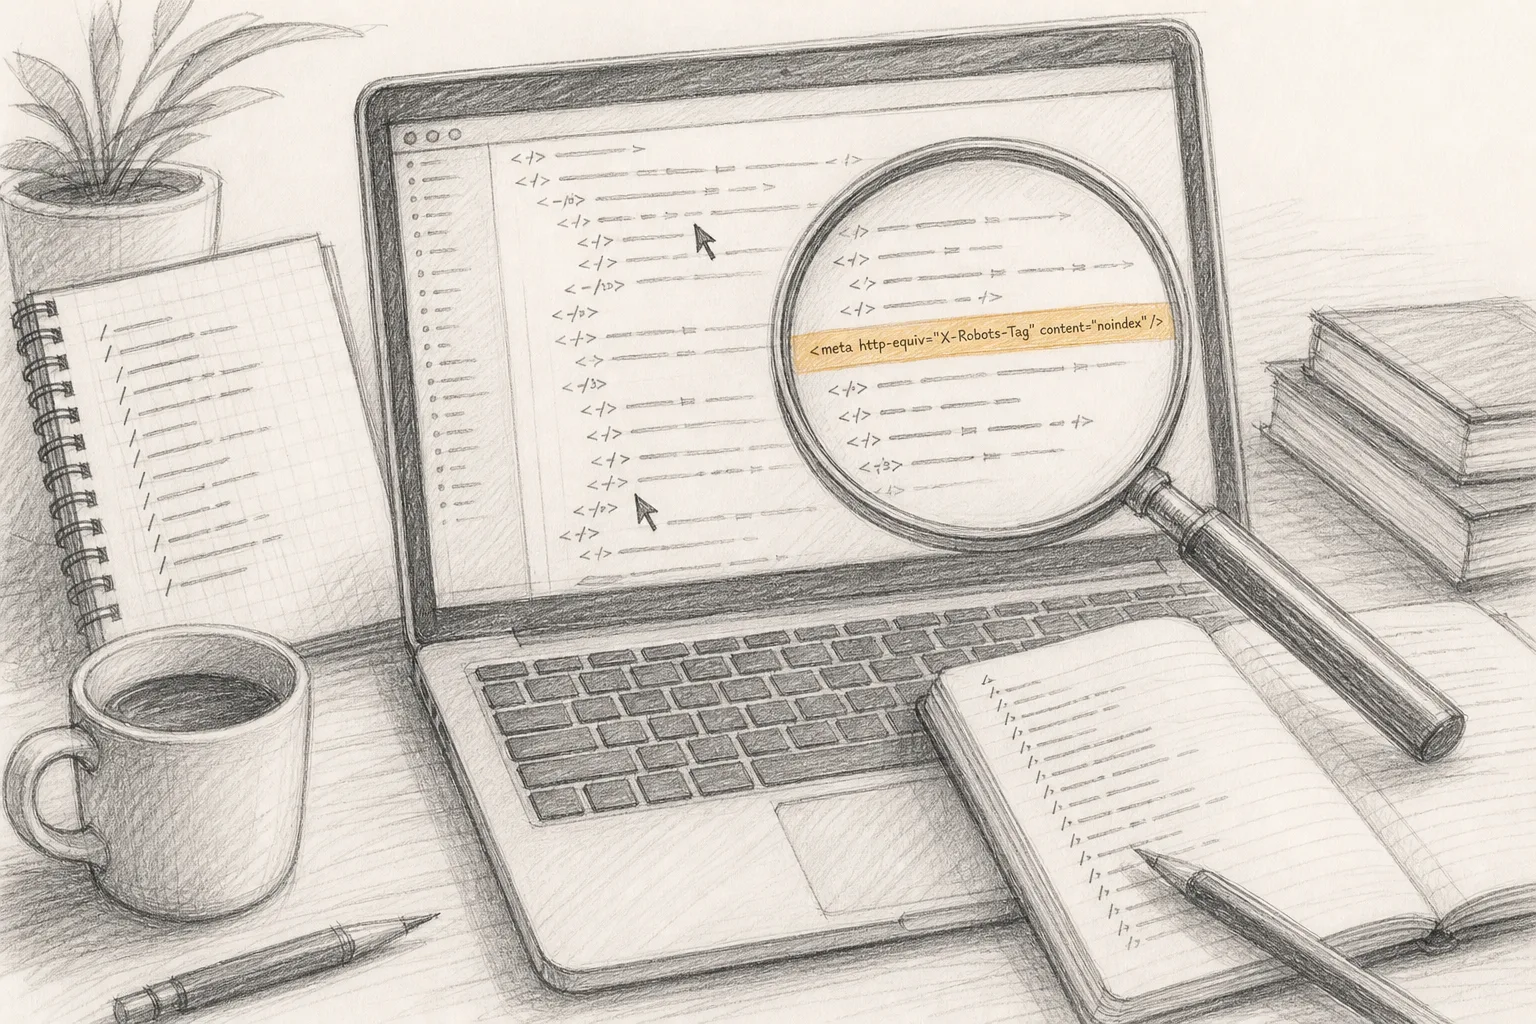
Check the robots meta tag and the X-Robots-Tag header on every template. Run curl -sI on one URL per template and look for X-Robots-Tag: noindex. Then search the raw HTML for name="robots" and read its content value. Do both: a header and a meta tag are set in different places and break independently. Where it fails: the home page is fine, but a deeper template (blog posts, docs, product pages) reads a different config value and ships noindex. Recovery: remove the directive, redeploy, then request reindexing of the most important affected URLs in Search Console rather than waiting for a natural recrawl.
Read the canonical tag on each template and confirm the host. The canonical should be an absolute URL on your production host, with the protocol and www choice you actually serve, pointing at the page itself (or at its intended original). A canonical on a preview host, a staging subdomain, localhost, or a plain HTTP address when you serve HTTPS tells search engines another URL is the real one. Where it fails: the canonical is built from a base URL variable that has a sensible default only in development. Recovery: set the production base URL explicitly, fail the build if it is missing, and re-check every template, not just the one you noticed.
Follow every changed or removed route hop by hop. For each old URL the release renamed or removed, run curl -sIL and read every hop. You want one redirect, a permanent one, straight to a final URL that returns 200. Count the hops: an old redirect pointing to another redirect, plus a trailing slash rule, plus an HTTP to HTTPS rule, quickly becomes a chain. Where it fails: the new redirect targets a URL that itself redirects, or two rules disagree and loop. Recovery: point every old URL directly at its final destination, update internal links to the final URL so crawlers stop discovering the old one, and update the sitemap.
Compare the raw HTML with the rendered page. Fetch the page with curl -s and search the output for a sentence you know appears in the body text, the main heading and the internal links. Then compare it with what the browser renders. If the sentence is visible in the browser but absent from the raw HTML, the content now depends on JavaScript running. Where it fails: a refactor moves data fetching into the browser, and the page still looks perfect to everyone testing it in a browser. Recovery: render the content on the server or at build time for any page you want found or quoted; leave client-side rendering for interactive parts that do not need to be indexed.
Check the certificate on every host you serve. In a browser, open the certificate details for the main host, the www and bare variants, and any subdomain the release added. From a terminal, openssl s_client -connect HOST:443 -servername HOST followed by openssl x509 -noout -dates prints the validity dates, with HOST replaced by each host name. Confirm the certificate covers each host name and is not close to expiry. Where it fails: the main host renews automatically, but a newly added subdomain or a CDN in front of it does not. Recovery: renew or issue the missing certificate, then check that the renewal job is actually scheduled, because a certificate that renewed by hand will lapse again.
Re-run a full scan of the live site and compare it with your last one. The manual steps above check six known failure modes on a handful of URLs. A scan covers the checks you did not think to repeat. The readiness scan on LaunchScaler takes only a URL, no account, and is grouped into seven areas: search, AI visibility, backlinks, security, compliance, speed and visual, and does it work. The free scan runs 156 checks across 6 of those 7 areas. Every check scores out of 100, so you can line up this release's result against the previous one area by area and see which checks moved. Where it fails: a scan run once, after the release, with nothing to compare it with, tells you the current state but not what changed. Recovery: keep each scan result with the release it followed, so the next comparison has a reference point.
Watch Search Console and Bing Webmaster Tools for the next several days. Look at the page indexing report for new "Excluded by noindex tag", "Blocked by robots.txt", "Alternate page with proper canonical tag" or "Page with redirect" entries, and use URL Inspection on the URLs the release touched. These reports lag the live site, so they confirm what steps 2 to 7 found rather than replacing them. Where it fails: a team treats an empty report on day one as proof nothing broke. Recovery: treat Search Console as the second signal, and set a reminder to look again after the next crawl of the affected pages.
Schedule the next comparison before you close the release. Regressions also arrive between deploys: a certificate lapses, a hosting platform changes a default, a third-party script lands in a tag manager without any code change. Put a recurring re-check in a calendar, a cron job, or a monitoring service, against the same baseline URLs. Where it fails: the check runs only when someone remembers, which is usually after traffic has already moved. Recovery: make the schedule independent of the release cycle so it runs whether or not anyone shipped.
Which steps can you automate in CI, and which need production?
A genuine choice exists here, and one condition decides it: whether the check depends on configuration that only exists in production.
Run in CI, before merge: checks against built output where the production config is already applied. A test can fail the build if any page's HTML contains noindex, if the canonical host is not your production host, if robots.txt contains Disallow: /, or if a known content sentence is missing from server-rendered HTML.
Run against production, after deploy: anything a layer outside your build can change. That means the served robots.txt, response headers added by a CDN or platform, redirects defined at the edge, and certificates. CI cannot see these, because they do not exist in your repository.
If your build reads environment variables at runtime rather than at build time, move the noindex and canonical checks to the production side too, because the CI build will not hold the values production uses. Most small teams end up with a short CI test for the HTML checks and a post-deploy script for the rest.
A worked example: one weekly release, every step
A two-person team ships a weekly release of a web app with a marketing site and a blog on the same domain. This week's release does three things: it renames /features to /product, rebuilds the pricing page as an interactive component, and adds a docs. subdomain.
Baseline. Before merging, one of them runs a small script that saves headers and raw HTML for the home page, /features, /pricing, one blog post and robots.txt. The last scan result from the previous release is already in the release notes.
robots.txt. After deploy, the served robots.txt matches the baseline. Pass.
Robots meta and header. The home page and blog post are clean. The new docs subdomain returns X-Robots-Tag: noindex, because the docs platform ships that header by default until a setting is switched. That is a regression on a host they want indexed. They switch the setting and re-check the header.
Canonicals. The home page canonical is correct. The rebuilt pricing page has a canonical on the preview host, because the new component builds its canonical from a different variable than the rest of the site. They point both at the same production base URL and redeploy.
Redirects./features now redirects to /product. Following it with curl -sIL shows three hops: /features to /features/ (a trailing slash rule), to /product, to /product/. They replace the rule with a single permanent redirect from /features to /product/ and change the internal links in the navigation and footer to point at /product/ directly.
Rendered HTML. On the rebuilt pricing page, curl -s returns the page title and an empty container. The plan names and prices only appear after JavaScript runs. A browser shows everything; a crawler that does not render sees nothing to index or quote. They move the plan data into server-rendered markup and keep the interactive toggle on top of it.
Certificate. The main host is fine. docs. serves a valid certificate issued by the docs platform. Pass.
Scan comparison. They run the free readiness scan on the production URL and set the result beside last week's. The search area moved, which matches what they already fixed; the AI visibility area also moved, and the checks behind it point at the same pricing page. After the redeploy they scan again and the moved checks are back where they were.
Search Console. They inspect /product/ and the pricing page, request indexing for both, and add a reminder to read the page indexing report after the next crawl.
Four of six checks found something. None of the four would have shown up in a traffic graph that day, and none was caused by a change anyone thought was about search.
Template: the post-deploy SEO checklist
Copy this into your release notes or pull request template and tick it on every release.
Before the release
List the URLs this release adds, renames or removes
Save production headers, raw HTML, canonical and robots meta for: home page, one URL per template, every touched URL
Save the served robots.txt
Note the result of the last scan of the live site
Within minutes of the deploy
robots.txt served from production matches the baseline, and no Disallow: / under User-agent: *
No X-Robots-Tag: noindex header on any template you want indexed
No noindex in the robots meta tag on any template you want indexed
Every canonical is absolute, on the production host, with the right protocol and www choice
Every renamed or removed URL reaches its final 200 page in one permanent redirect
Internal links and the sitemap point at final URLs, not redirects
A known body sentence, the main heading and internal links appear in the raw HTML of each template
Certificates are valid and cover every host and subdomain served
A fresh scan of the live site is compared with the previous one, check by check
In the days after
URL Inspection run on every touched URL
Page indexing report read after the next crawl, for new noindex, robots.txt, canonical or redirect exclusions
The next scheduled re-check is on the calendar
How do you tell a regression from an algorithm update or a seasonal dip?
When traffic moves, the checklist above is also the fastest way to rule your own site in or out. Run steps 2 to 7 against production. If any of them fails, you have a concrete regression with a date you can match to a release, and that is where to start. If all of them pass and your scan result has not moved since before the drop, the cause is more likely outside your site: demand for the query changed, competitors changed, or search engines changed how they rank or present results.
Two details narrow it further. A regression usually hits one template or one set of URLs, the ones the faulty change touched, while an outside change usually spreads unevenly across many unrelated pages. And a regression has a date that lines up with a deploy or an infrastructure change; check your release log and your hosting provider's change notes for the days before the drop started.
What a single post-deploy check cannot see
Every step above runs at one moment. The list of failures that arrive between those moments is not short:
a certificate whose renewal job silently stopped
a hosting or CDN default that changes without a deploy on your side
a third-party script added through a tag manager, which can affect security headers or page speed
an uptime problem that lasts long enough for a crawler to hit it and not long enough for you to notice
a content editor publishing a page with the wrong template settings
This is the gap a recurring check closes. The question is only who runs it. You can run the checklist yourself on a fixed weekday, write a scheduled job that fetches your baseline URLs and alerts on differences, or use a service that re-runs the comparison for you. A self-written job is the right choice when the failure modes are specific to your stack and you are comfortable maintaining it; a service is the right choice when you would rather not own another script.
Start with this week's release. Before you merge, save the baseline in step 1; after you deploy, run steps 2 to 7 against production and put the checklist in your pull request template so the next release inherits it.
Then decide who runs the comparison between deploys. If you would rather not maintain it yourself, Watch re-runs the same readiness scan every two weeks for one website, checks uptime on your health endpoint in between, and emails a diff showing which checks moved and by how many points. It is measured against exactly the same bar as the free scan: it tells you sooner when a check fails, and it never tells you a failing check passed. It is $29/mo for one domain, and you can cancel whenever you like. Start watching.
Short answers to related questions
How long after a deploy do SEO problems show up in search?
That depends on when crawlers next fetch the affected pages, which you do not control. A broken certificate or a redirect loop affects visitors immediately; a noindex or a wrong canonical takes effect page by page as each one is recrawled. That uncertainty is the reason to check production yourself rather than wait for a report.
Should a staging site be blocked with noindex or with a password?
A password, or another form of access control, is the safer choice, because it keeps staging out of the index without putting a noindex directive into the codebase that can travel to production. If you must use noindex on staging, set it from the environment and add the CI check that fails the build when it appears in production output.
Does fixing a regression restore rankings immediately?
No one can promise that. Once the fix is live, search engines need to recrawl and reprocess the affected pages, and what they do next is their decision. What you can do is shorten the wait: fix the cause, request reindexing of the most important URLs in Search Console, and make sure internal links and the sitemap point at the corrected URLs.
Do AI answer engines read client-side rendered pages?
Many AI fetchers request the raw HTML and do not run JavaScript, so content that only appears after rendering may be invisible to them. Step 6 is the practical test: if a sentence is missing from the curl output, assume an answer engine cannot quote it.
A full website audit checks seven areas, not just SEO: search, AI visibility, backlinks, security, compliance, speed and visual, and whether your site works.
The free SEO tools that read your live site: Search Console, Bing Webmaster Tools, PageSpeed Insights, Rich Results Test, a crawler and a readiness scan, in order.
A full SEO audit gives every finding its measured signal, the threshold it failed, evidence from your page and the exact fix, ordered by what breaks first.