Auditing
fundraisly.com
- Search
- AI visibility
- Backlinks
- Security
- Compliance
- Does it work
- Speed & visual
Check 7 of 7
Speed & visual
Diffing against baseline
https://fundraisly.comrun am551g
Audit report

Fundraisly
fundraisly.com
Investor meeting booking and guidance for founders
Last scanned Sep 14, 2026
Launching
You are clear to go live.
Pick a day, or launch today with Premium.
Executive summary
- 49ComplianceConsent, policy pages, and the disclosures you owe.30/30measured
- —Speed & visualHow fast it loads and how it renders at every size.24/295 grey
- 83AI visibilityWhether answer engines cite you when they should.20/13measured
- 86SecurityHeaders, TLS, and what an attacker sees first.29/29measured
- 92SearchWhether search engines can find, read and rank the page.28/28measured
- 97Does it workLinks, forms and flows that fail silently.27/27measured
- —BacklinksWho links to you, and whether those links carry weight.—not measured
What to fix
Ordered by what it costs you, not by which check found it.
In order of what it costs you
- 01ComplianceWCAG 1.1.1 Non-text Content (image alt text)Regulatory and legal exposure on consent, disclosures and accessibility.Add descriptive alt to informative images and alt="" to decorative ones.
- 02Speed & visualMain-thread work during loadA slow or broken render makes visitors bounce, and Google ranks it lower.Reduce JS execution (see speed-unused-js), memoize expensive renders, offload heavy pure computation to a Web Worker, and yield long tasks.
- 03Speed & visualUnused JavaScript shipped to the clientA slow or broken render makes visitors bounce, and Google ranks it lower.Code-split by route, dynamic-import below-the-fold and interaction-only components, tree-shake dead exports, and lazy-load third-party SDKs after load.
- 04SecurityNo clickjacking protection (frame-ancestors / X-Frame-Options)Leaves the site open to attack, or gets it flagged as unsafe in browsers.Add `Content-Security-Policy: frame-ancestors 'none'` (or 'self'), and for legacy browsers also send `X-Frame-Options: DENY`.
- 05SecurityNo Content-Security-PolicyLeaves the site open to attack, or gets it flagged as unsafe in browsers.Start with a report-only policy, then enforce e.g.
- 06ComplianceWCAG 1.3.1 / 2.4.4 Heading order & discernible link namesRegulatory and legal exposure on consent, disclosures and accessibility.Insert the missing <h2> levels so headings never skip; give icon links an aria-label and make repeated 'Read more' links unique or add aria-label with context.
- 07Speed & visualLab performance score (weighted)A slow or broken render makes visitors bounce, and Google ranks it lower.Prioritize by weight: TBT and LCP together are 55% of the score, so shipping the hydration-bundle and LCP-image fixes above moves the number most.
- 08SecuritySPF record and default qualifierLeaves the site open to attack, or gets it flagged as unsafe in browsers.Tighten the trailing qualifier to -all once every legitimate sending source is enumerated in the record.
- 09SecurityThird-party scripts lack Subresource IntegrityLeaves the site open to attack, or gets it flagged as unsafe in browsers.Add an SRI hash and crossorigin to each pinned third-party script: `<script src=...
- 10SearchContent has no author byline or verifiable author entity (Who gap)Search engines can't find, read or rank the page: lost organic traffic.Add a real byline linking to an author page with bio and credentials, and Person author schema with `url`/`sameAs`; match the schema name to the visible byli…
+ 19 more below, itemised by area.
What we saw
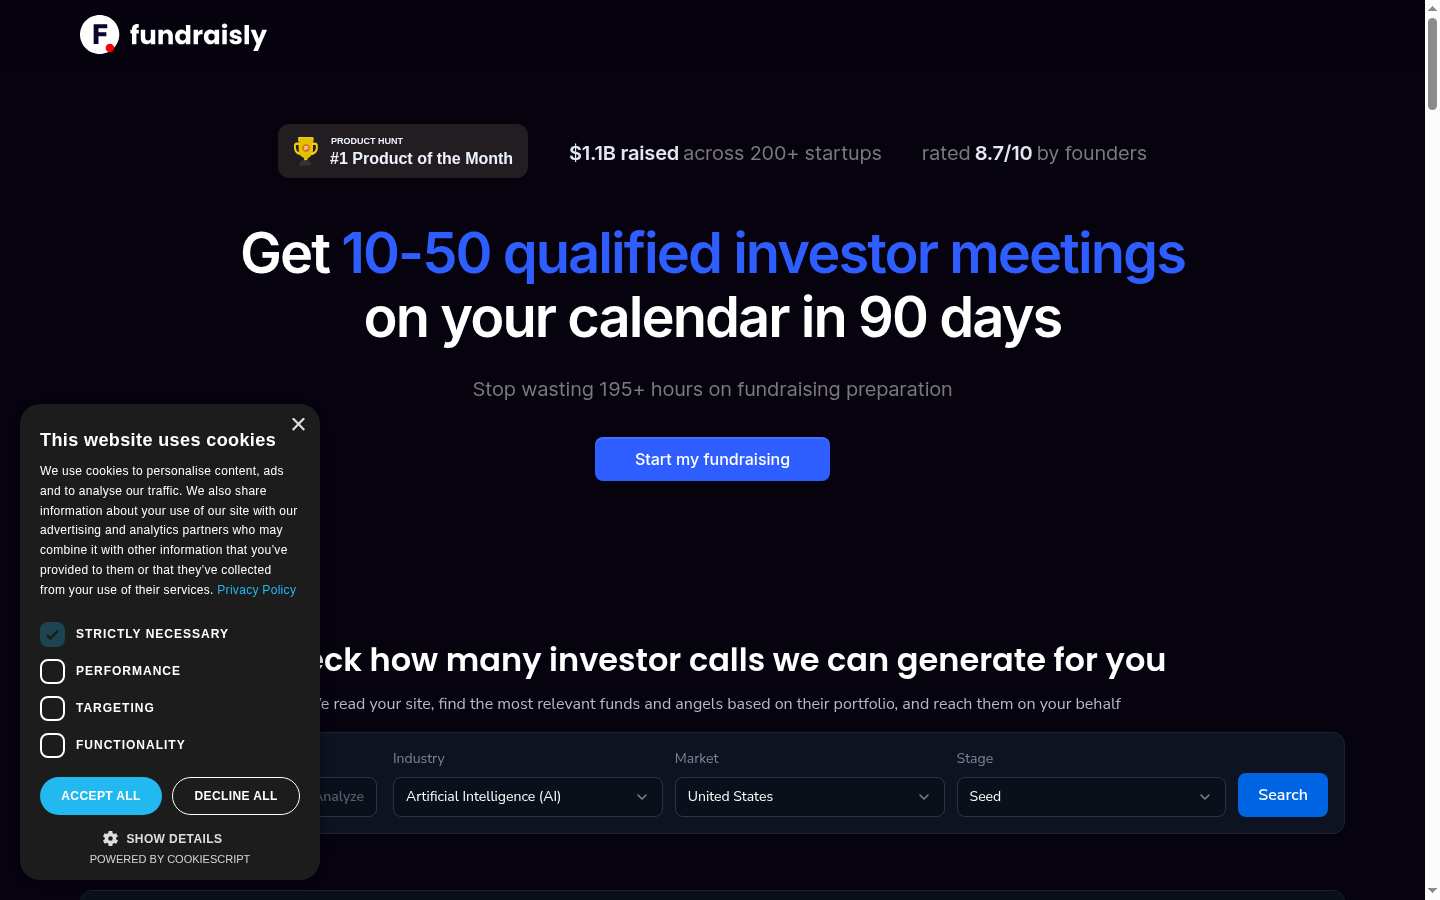
Agentic Browsing · can an AI agent use this site
A Lighthouse factor since May 2026: whether an autonomous agent (ChatGPT agent mode, Claude computer-use) can reach the page, read what it is, and complete a task.
The agent's fetcher can reach the page and gets real content, not a challenge or a blank shell.
5 signals · scored 100
The page is structured so the agent can read what it is: labels, semantics, language and schema.
6 signals · scored 43
The agent can actually act: controls are wired and keyboard-operable, with no overlay trapping it.
4 signals · scored 100
Search
Whether search engines can find, read and rank the page.
The score grades what a crawler can reach and how your pages describe themselves.
1 of 25 measured failing
- Needs work
Title tag exceeds display width and gets truncated or rewritten by Google
- Measured
- 70-character <title>
- Threshold
- Google truncates title links at ~600px on desktop (roughly 50-60 chars). Zyppy's 80k-page study: titles >70 chars are rewritten ~99.9% of the time; the 51-55 char band has the lowest rewrite rate at ~40%.
- Observed
- <title>Fundraisly - Guided fundraising with investor meetings booked for you.</title>
- Fix
- Rewrite the title to 50-60 characters / under 600px, front-load the primary term, and move the brand to the end after a dash so the meaningful part survives truncation.
- Needs work
Content images are missing alt text, losing image-SEO and accessibility signals
- Measured
- 1 of 102 <img> lack an alt attribute
- Threshold
- Web Almanac 2025: the median page has alt present on only ~60% of images, ~15% with blank alt and ~15% missing entirely. Meaningful content images should carry descriptive alt; decorative-only images may use alt="".
- Observed
- 1/102 images with no alt attribute (an explicit alt="" decorative marker is not counted) e.g. https://i.ytimg.com/vi_webp/pkRCPWSh4mE…
- Fix
- Write concise descriptive alt for every content-bearing image (name the subject/function, not "image123"); reserve alt="" strictly for purely decorative graphics.
- Needs work
Heading levels are skipped or multiple H1s compete, so structure is unparseable
- Measured
- 0 H1
- Threshold
- H2 is the most-adopted structural tag (~72% of pages, Web Almanac 2025); a well-formed page uses one H1 then a nested H2/H3 outline. Multiple co-equal H1s and skipped levels blur which heading owns the page.
- Observed
- outline: H2 H2 H2 H2 H2
- Fix
- Collapse to one H1, use H2 for major sections and H3 for sub-points without skipping a level; reserve heading tags for actual headings, not styling.
- Needs work
Content has no author byline or verifiable author entity (Who gap)
- Measured
- article content without an author
- Threshold
- Google's 'Who/How/Why' guidance asks: is it self-evident who authored the content, and do bylines link to author background? For Article structured data Google recommends an `author.url` to a page that uniquely identifies the author, since a name alone is a weak, unverifiable signal.
- Observed
- no author schema property and no visible byline
- Fix
- Add a real byline linking to an author page with bio and credentials, and Person author schema with `url`/`sameAs`; match the schema name to the visible byline exactly.
- Needs work
No concise answer passage exists to win a featured snippet / AI answer
- Measured
- no 40–70 word standalone passage near the top
- Threshold
- Featured-snippet studies: paragraph featured snippets average ~43 words and 40-60 word passages account for roughly half of paragraph snippets; capture probability falls sharply beyond ~70 words. Pages lacking a crisp, self-contained answer forfeit position-zero and AI-Overview citation.
- Observed
- early paragraph word counts: 2, 2, 3, 3, 1, 1
- Fix
- Add a 40-55 word direct answer immediately after the H1/question heading, phrased as a self-contained definition, plus a supporting list/table for list and table snippets.
- Passing
/ not disallowed
- Bar met
- A page intended for search must NOT be Disallowed. A Disallowed URL can still be indexed URL-only (no snippet) if linked, but its content is never crawled
- Observed
- robots.txt has no Disallow rule matching /
- Passing
no noindex directive
- Bar met
- No `noindex` token in either the meta robots tag or X-Robots-Tag header. When Googlebot sees noindex it removes the page from results regardless of inbound links
- Observed
- neither meta robots nor X-Robots-Tag carries noindex
- Passing
no conflicting directives
- Bar met
- noindex only works if the page is crawlable, so the two directives are mutually defeating. A robots-blocked URL with noindex can still appear URL-only in results
- Observed
- disallowed=false, noindex=false
- Passing
canonical is self-referencing
- Bar met
- The canonical target must return 200 and be indexable. A canonical to a redirect/404/noindex sends a contradictory signal that Google may ignore, choosing its own canonical
- Observed
- canonical https://fundraisly.com/ == fetched URL (200)
- Passing
largest sitemap: 108 URLs / 0.0MB
- Bar met
- ≤ 50,000 URLs AND ≤ 50MB uncompressed per file; split into a sitemap index above either limit
- Observed
- https://fundraisly.com/sitemap.xml within 50k-URL and 50MB caps
- Passing
descriptive title present
- Bar met
- Google: every page needs distinct, descriptive title text; half-empty titles like `<title>| Site Name</title>` and vague labels like 'Home' are called out as issues that trigger Google-generated replacements. 98.6% of pages carry a non-trivial <title> (Web Almanac 2025), so an empty one is a clear outlier.
- Observed
- <title>Fundraisly - Guided fundraising with investor meetings booked for you.</title>
- Passing
100-character meta description
- Bar met
- Desktop snippets truncate at ~920px (~155-160 chars); mobile at ~680px (~110-120 chars). The Web Almanac 2025 median description is 274 chars, well past the cutoff, so most of the copy never renders.
- Observed
- <meta name="description" content="We put investor meetings on your calendar. Founders average 20–40 investor meetings within 90 days.">
- Passing
1242 words of body text in raw HTML
- Bar met
- Backlinko's 11.8M-result analysis found page-one results average ~1,447 words and position #1 ~1,890. Word count is not a ranking factor, but ~120 words on an explanatory page is a thin-content signal; Google's guidance asks whether content is a "substantial, complete, or comprehensive" treatment of the topic.
- Observed
- main-content extraction of https://fundraisly.com/ → 1242 words
- Passing
self-referencing canonical
- Bar met
- Exactly one canonical, absolute URL, placed in the <head>; on a standalone page it should be self-referencing. rel=canonical is a strong consolidation signal. A wrong target hands ranking to another URL
- Observed
- canonical → https://fundraisly.com/ matches the page
- Passing
no redirect on the requested URL
- Bar met
- Googlebot follows up to 10 redirect hops per URL before giving up; keep chains to a single hop. Each extra hop consumes crawl resources and dilutes signals
- Observed
- https://fundraisly.com → 200 with no hop
- Passing
HTTP 200 with 1242 words of content
- Bar met
- A missing or empty page must return 404 or 410, not 200. Soft 404s are load-render-discard cycles that Google flags and that clutter the index
- Observed
- no not-found signal in title/body of https://fundraisly.com/
- Passing
sitemap referenced in robots.txt
- Bar met
- A valid XML sitemap should exist and be referenced via a `Sitemap:` line in robots.txt (or submitted in Search Console). Sitemaps aid discovery and carry lastmod signals
- Observed
- Sitemap: https://fundraisly.com/sitemap.xml
- Passing
10 sampled sitemap URLs all return 200
- Bar met
- Every sitemap URL should be a canonical, indexable page returning 200. Redirects/404s/noindexed URLs in a sitemap are dirt signals that reduce trust in the file
- Observed
- no redirect/404 in sampled <loc> entries
- Passing
no http:// subresources
- Bar met
- Zero http:// subresources on an HTTPS page. Browsers block active mixed content (JS/CSS/iframes) outright; passive mixed content is flagged/auto-upgraded
- Observed
- all subresources are https or protocol-relative
- Passing
no metadata stranded outside <head>
- Bar met
- Only head-permitted elements before critical meta. An invalid element implicitly closes <head>, so any canonical/robots/hreflang after it is parsed into <body> and ignored. ~10.6% of pages have invalid <head> HTML (2024)
- Observed
- canonical/robots/hreflang resolve inside <head>, not pushed into <body>
- Passing
meta description present (100 chars)
- Bar met
- Only 67.7% of pages carry a meta description (Web Almanac 2025). A 20k-keyword study found Google rewrites descriptions ~62.8% of the time even when supplied, and a supplied description actually appears only ~37% of the time, so a missing one guarantees a machine-scraped snippet.
- Observed
- <meta name="description" content="We put investor meetings on your calendar. Founders average 20–40 investor meetings within 90 days.">
- Passing
25 internal links on the page
- Bar met
- Web Almanac 2025: the median page has ~43 internal links (90th percentile ~174). A content page with a handful of internal links and no inbound contextual links from related pages is effectively orphaned for topic-authority purposes.
- Observed
- 25 internal of 44 total anchors on https://fundraisly.com/
- Measured, nothing to grade
hreflang annotations lack reciprocal return tags, so Google ignores them
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- hreflang must be bidirectional: if A lists B, B must list A, and both must include a self-referencing entry. Missing return tags cause Google to drop the annotations
- Fix
- Ensure every page in the cluster lists all variants including itself, and each target reciprocates; add an `x-default` for the language selector
- Measured, nothing to grade
hreflang URLs point at redirecting or non-200 targets instead of the final canonical
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- hreflang targets must return 200 and be the canonical, self-referencing URL. Google does not follow redirects for hreflang, so a 3xx target voids the annotation
- Fix
- Point every hreflang href at the final HTTPS, trailing-slash-correct, 200-returning canonical URL
- Measured, nothing to grade
Structured data is present but missing required properties, so the page is ineligible for rich results
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- All required properties for the rich-result type must be present and valid; missing a required property disqualifies the item (warnings for recommended props do not). JSON-LD is Google's preferred format
- Fix
- Add the missing required properties for the type, validate against the Rich Results Test, and keep JSON-LD content consistent with the visible page
AI visibility
Whether answer engines cite you when they should.
The score grades whether an answer engine can fetch your pages and whether it finds enough on them to cite you.
2 of 19 measured failing
- Needs work
No /llms.txt curated map for LLM agents (advisory, not a ranking factor)
- Measured
- no usable /llms.txt (HTTP 404)
- Threshold
- WARN only, never fail. Google (Illyes, Jul 2025; Mueller: 'no AI system currently uses llms.txt') consumes nothing from it, and an analysis of 137k sites found 97% of published llms.txt files were never requested. Perplexity/Claude/coding agents (Cursor, Copilot) do retrieve it, so it is a low-cost nicety, not a defect.
- Observed
- GET /llms.txt → 404 — advisory only, not a defect
- Fix
- Optional: publish a Markdown /llms.txt (H1 site name, blockquote summary, H2 sections of curated links) if you serve docs/agent audiences. Do not prioritize this over robots.txt, SSR, or schema, since nothing consumes it for search ranking.
- Needs work
XML sitemap missing or lacks lastmod, so crawlers can't detect changed pages
- Measured
- sitemap present but 0 of 108 <url> entries carry <lastmod>
- Threshold
- Warn when no sitemap is discoverable via robots.txt/root, or when <lastmod> is absent/static. lastmod is the primary machine signal telling AI crawlers which pages changed and when. Without it they re-crawl blindly and miss updates on their limited budget.
- Observed
- https://fundraisly.com/sitemap.xml → 108 <url>, no <lastmod>
- Fix
- Publish a sitemap, reference it in robots.txt (Sitemap:), and emit accurate per-URL <lastmod> reflecting genuine content changes. Keep lastmod consistent with dateModified and the visible date.
- Needs work
No Wikipedia or Wikidata entity for the brand
- Measured
- no Wikipedia/Wikidata entity linked for "Fundraisly"
- Threshold
- Warn on absence for an early-stage brand; the signal is weighted heavily because Wikipedia and Wikidata are among the most-referenced sources in LLM training and retrieval, and they anchor the entity an engine attributes facts to. Notability rules mean many small brands cannot get a page, so this is a signal, not an obligation.
- Observed
- no wikipedia.org/wikidata.org in sameAs; guessed title https://en.wikipedia.org/wiki/Fundraisly → 404 (signal, not an obligation for an early-stage brand)
- Fix
- Where the brand meets notability, pursue a Wikipedia article and a Wikidata item, and link both from Organization sameAs. Where it does not, strengthen the other entity anchors (Crunchbase, LinkedIn, G2) that engines fall back to.
- Passing
no retrieval bot explicitly Disallowed
- Bar met
- Any Disallow that matches OAI-SearchBot, Claude-SearchBot, or PerplexityBot on citation-eligible paths is a fail. OpenAI states sites opted out of OAI-SearchBot 'will not be shown in ChatGPT search answers.'
- Observed
- OAI-SearchBot / Claude-SearchBot / PerplexityBot are not blocked by an explicit robots.txt group on /
- Passing
no retrieval bot caught by a wildcard block
- Bar met
- Retrieval bots must resolve to Allow. A wildcard or 'block all AI' rule that also matches OAI-SearchBot / Claude-SearchBot / PerplexityBot is a fail; robots.txt is longest-match/most-specific per agent, so a specific Allow is required to override `*`.
- Observed
- retrieval bots are either explicitly handled or the wildcard group does not Disallow /
- Passing
bot UA → HTTP 200, no challenge
- Bar met
- Fail if any retrieval bot UA (OAI-SearchBot, PerplexityBot, Claude-User/Claude-SearchBot) receives a non-2xx or a challenge page. WAF/firewall rules run before robots.txt, so a WAF block overrides a robots.txt Allow. Bot Fight Mode and 'block AI bots' managed rules commonly false-positive here.
- Observed
- OAI-SearchBot-UA GET returned 200 with real content, matching the browser-UA baseline (200)
- Passing
ChatGPT-User and Claude-User both get a 2xx with real HTML (baseline 200)
- Bar met
- The ChatGPT-User and Claude-User user-agents must each receive a 2xx with real, non-trivial HTML content, with no WAF/CAPTCHA/JS-challenge interstitial and not a blank client-side-rendered shell. These are the on-demand agent fetchers ChatGPT agent mode and Claude computer-use send when a user asks them to complete a task on a live site (distinct from the retrieval/index bots OAI-SearchBot / PerplexityBot). If either UA is blocked or served nothing, an autonomous agent cannot read or act on the page.
- Observed
- ChatGPT-User → HTTP 200, ~11067 words of real HTML; Claude-User → HTTP 200, ~11067 words of real HTML
- Passing
0 of 11 sampled URLs broken (0.0%)
- Bar met
- Warn above ~5% broken-link ratio. Vercel measured ChatGPT wasting 34.82% and Claude 34.16% of fetches on 404s vs Googlebot's 8.22%. AI crawlers have far weaker URL-validation, so dead links disproportionately consume their limited budget and starve real pages.
- Observed
- 6 internal links + 5 sitemap URLs sampled; broken ratio within the ~5% budget
- Passing
0 of 6 internal links redirect
- Bar met
- Warn if internal links depend on redirects (any chain > 1 hop is worse). Vercel measured ChatGPT spending an extra 14.36% of fetches following redirects vs Googlebot's 1.49%. Non-rendering bots waste budget and sometimes drop chained targets.
- Observed
- internal links resolve to final 200 URLs with no chained hops
- Passing
missing URL correctly returns HTTP 404
- Bar met
- Warn on any soft 404 (200 status on a not-found page). Non-rendering AI crawlers rely on status codes to decide what to store; a 200 on an error page gets ingested as real content and can surface as a garbage citation, while also masking the broken-link waste in aeo-404-crawl-waste.
- Observed
- GET a nonexistent slug → 404; AI crawlers can skip dead URLs
- Passing
no AI bots blocked; retrieval bots allowed
- Bar met
- Legitimate configuration, so this passes. Blocking GPTBot/ClaudeBot only affects model-training corpus, not live citations. Training accounted for ~7-8x search-crawl volume in 2025, so this is a common and valid data-rights choice.
- Observed
- neither training nor retrieval bots are Disallowed — nothing to flag
- Measured, nothing to grade
Structured data is present but malformed, so parsers discard it
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- Fail on any JSON that does not parse or references an invalid @type/required-property violation. Broken JSON-LD is equivalent to no structured data. The parser drops the whole block, not just the bad field.
- Fix
- Validate every JSON-LD block (JSON must parse; @type must be a real schema.org type; include required properties). Fix the trailing comma and correct 'Organisation' → 'Organization'. Run schema validation in CI.
Backlinks
Who links to you, and whether those links carry weight.
The score grades your inbound links: what is broken, what looks bought or spammy, how your anchors read, how the profile is growing, and where competitors are linked and you are not.
Not measured on this scan
Security
Headers, TLS, and what an attacker sees first.
The score grades your certificate and the headers your server sends back.
2 of 26 measured failing
- Failing
No Content-Security-Policy
- Measured
- No Content-Security-Policy header on the primary HTML document.
- Threshold
- A CSP must be present. Observatory: csp-not-implemented = -25; a strong policy (csp-implemented-with-no-unsafe-default-src-none) earns +10.
- Observed
- content-security-policy: (absent) content-security-policy-report-only: (absent)
- Fix
- Start with a report-only policy, then enforce e.g. `default-src 'self'; object-src 'none'; base-uri 'self'; frame-ancestors 'none'; upgrade-insecure-requests`.
- Failing
No clickjacking protection (frame-ancestors / X-Frame-Options)
- Measured
- Neither X-Frame-Options nor a CSP frame-ancestors directive is present — the page can be framed by any origin.
- Threshold
- Set X-Frame-Options: DENY|SAMEORIGIN or CSP frame-ancestors. Observatory: x-frame-options-not-implemented = -20; frame-ancestors via CSP (x-frame-options-implemented-via-csp) = +5.
- Observed
- x-frame-options: (absent) content-security-policy frame-ancestors: (absent)
- Fix
- Add `Content-Security-Policy: frame-ancestors 'none'` (or 'self'), and for legacy browsers also send `X-Frame-Options: DENY`.
- Needs work
HSTS present but not preload-eligible
- Measured
- HSTS present but not preload-eligible: includeSubDomains missing, preload token missing.
- Threshold
- Preload list requires max-age >= 31536000 (1 year), includeSubDomains, and the preload token, plus an HTTP->HTTPS redirect on the same host. Observatory awards hsts-preloaded = +5.
- Observed
- strict-transport-security: max-age=31536000
- Fix
- Raise max-age to 31536000+, add the `preload` token (`max-age=63072000; includeSubDomains; preload`), then submit the apex domain at hstspreload.org.
- Needs work
Referrer-Policy not set to a privacy-preserving value
- Measured
- No Referrer-Policy header — the browser default applies rather than an explicit private policy.
- Threshold
- Send a private policy such as no-referrer or strict-origin-when-cross-origin. Observatory: referrer-policy-private = +5; referrer-policy-unsafe (e.g. unsafe-url) = -5.
- Observed
- referrer-policy: (absent)
- Fix
- Add `Referrer-Policy: strict-origin-when-cross-origin` (or `no-referrer` for maximum privacy).
- Needs work
No Permissions-Policy restricting powerful features
- Measured
- No Permissions-Policy header — camera, microphone, geolocation and payment are allowed by default.
- Threshold
- Explicitly deny unused features. OWASP recommends locking each feature to () or (self), e.g. camera=(), microphone=(), geolocation=(), payment=(). (Not scored by Observatory; OWASP best practice.)
- Observed
- permissions-policy: (absent)
- Fix
- Emit a deny-by-default policy, e.g. `Permissions-Policy: camera=(), microphone=(), geolocation=(), payment=(), usb=()`, enabling only what the app uses.
- Needs work
Third-party scripts lack Subresource Integrity
- Measured
- 4 of 4 cross-origin script(s) load without a Subresource Integrity hash.
- Threshold
- Cross-origin scripts should carry integrity + crossorigin. Observatory: sri-not-implemented-but-external-scripts-loaded-securely = -5; worst case (loaded over http without SRI) = -50.
- Observed
- <script src="//cdn.cookie-script.com/s/396990d72caad1fddf6450f8ae9fc560.js"> (no integrity=) <script src="https://www.googletagmanager.com/gtag/js?id=G-2EF1HDLDXS"> (no integrity=) <script src="https://events.framer.com/script?v=2"> (no integrity=) <script src="https://framerusercontent.com/sites/5gayWuh22MREN5Gv9lyAel/script_main.CP29bvI9.mjs"> (no integrity=)
- Fix
- Add an SRI hash and crossorigin to each pinned third-party script: `<script src=... integrity="sha384-..." crossorigin="anonymous">`. Only feasible for version-pinned assets.
- Needs work
security.txt disclosure-contact file
- Measured
- No security.txt at /.well-known/security.txt or the legacy /security.txt path.
- Threshold
- A security.txt SHOULD be served at exactly /.well-known/security.txt over HTTPS as text/plain, and MUST contain Contact and Expires fields per RFC 9116. Missing it is a minor readiness gap (a finder has no defined channel), not a vulnerability.
- Observed
- GET https://fundraisly.com/.well-known/security.txt -> 404 GET https://fundraisly.com/security.txt -> 404
- Fix
- Publish /.well-known/security.txt with at least `Contact: mailto:security@example.com` and a future-dated `Expires:` in RFC 3339 form. Serve it as text/plain; charset=utf-8 over HTTPS.
- Needs work
SPF record and default qualifier
- Measured
- A single SPF record is published but ends in ~all (softfail) rather than -all.
- Threshold
- Exactly one SPF TXT record MUST exist (multiple = permerror). It should end in -all (fail) for a domain whose sender set is known; ~all (softfail) is tolerated during rollout. +all (pass-all) is a fail: it authorizes the entire internet.
- Observed
- TXT fundraisly.com -> "v=spf1 include:_spf.google.com ~all"
- Fix
- Tighten the trailing qualifier to -all once every legitimate sending source is enumerated in the record. Keep total DNS lookups under the RFC 7208 limit of 10 to avoid permerror.
- Needs work
CAA records restricting certificate issuance
- Measured
- No CAA record at the apex — any public CA may issue a certificate for the domain.
- Threshold
- A CAA record SHOULD exist naming the authorized CA(s). With no CAA record, any public CA may issue for the domain, widening the mis-issuance surface. Its absence is a hardening gap, not an active exposure.
- Observed
- CAA fundraisly.com -> (empty answer section)
- Fix
- Publish CAA pinning your issuer, e.g. `example.com. CAA 0 issue "letsencrypt.org"` plus an `iodef` mailto for violation reports. Add issuewild to control wildcard issuance.
- Needs work
DNSSEC signing of the zone
- Measured
- The zone is unsigned — no DNSKEY records and the resolver did not set the Authenticated Data flag.
- Threshold
- DNSSEC SHOULD be enabled (a DS record at the parent, RRSIG/DNSKEY in the zone) so DNS answers, including the MX, TXT and CAA records the other checks rely on, cannot be forged in transit. Unsigned is common but leaves those records spoofable.
- Observed
- DNSKEY fundraisly.com -> 0 record(s); resolver AD flag: unset
- Fix
- Enable DNSSEC at your DNS provider and publish the resulting DS record through your registrar. Confirm the chain of trust validates end to end before relying on it.
- Passing
HSTS present with max-age=31536000 (>= 6 months).
- Bar met
- Header must be present with max-age >= 15768000 (6 months). Observatory: hsts-not-implemented = -20; max-age under 6 months (hsts-implemented-max-age-less-than-six-months) = -10; OWASP recommends max-age=63072000; includeSubDomains.
- Observed
- GET https://fundraisly.com/ -> 200 strict-transport-security: max-age=31536000
- Passing
No Access-Control-Allow-Origin header on the document response (no wildcard exposure).
- Bar met
- Do not expose authenticated data with a wildcard ACAO. Observatory: cross-origin-resource-sharing-implemented-with-universal-access = -50. A wildcard combined with Allow-Credentials: true is rejected by browsers and is a red flag.
- Observed
- GET https://fundraisly.com/ -> 200 access-control-allow-origin: (absent) access-control-allow-credentials: (absent) (only the document response is read; per-endpoint CORS is not enumerated from a URL)
- Passing
X-Content-Type-Options: nosniff is present, disabling MIME sniffing.
- Bar met
- Header value must be exactly `nosniff`. Observatory: x-content-type-options-not-implemented = -5; nosniff = 0 (clean).
- Observed
- x-content-type-options: nosniff
- Passing
No precise server/framework version strings are exposed in response headers.
- Bar met
- Response headers SHOULD NOT leak precise version strings (Server, X-Powered-By, X-AspNet-Version). A version banner lets an attacker map known CVEs directly to the host. Disclosure is a warn: it eases reconnaissance rather than being an exploit itself.
- Observed
- server: Framer/bea9510 x-powered-by: (absent) x-aspnet-version: (absent)
- Passing
No http:// subresources referenced in the pre-JS HTML.
- Bar met
- No http:// subresources on an https:// page. Observatory penalises insecure schemes in CSP passive content (csp-implemented-with-insecure-scheme-in-passive-content-only = -10; active = -20).
- Observed
- document: https://fundraisly.com/ (no http:// src/link references in the served HTML)
- Passing
No same-origin JS bundles were referenced to probe for source maps.
- Bar met
- Production source maps SHOULD NOT be publicly served: they reconstruct original, un-minified source (including comments and internal paths), enlarging the attacker's view of client logic. A reachable .map is a warn, not a breach.
- Observed
- probed bundles: (none referenced in HTML)
- Passing
/.git/HEAD is not served (HTTP 404).
- Bar met
- /.git/ MUST NOT be reachable over HTTP. A served .git lets an unauthenticated visitor reconstruct full source, commit history and any secrets ever committed. Any 200 (vs 403/404) on /.git/HEAD or /.git/config is a fail.
- Observed
- GET https://fundraisly.com/.git/HEAD -> 404
- Passing
/.env is not served (HTTP 404).
- Bar met
- /.env and sibling config files (.env.local, config.php.bak, wp-config.php~) MUST return 403/404, never 200. A served .env typically exposes database URLs, API keys and secret tokens. Any 200 with dotenv-shaped content is a fail.
- Observed
- GET https://fundraisly.com/.env -> 404
- Passing
No conventional phpinfo page, database dump or archive was reachable.
- Bar met
- Reachable database dumps or archives are a fail; a live phpinfo() page is at least a warn: it discloses full environment, loaded modules, paths and env vars, aiding targeted attack. Conventional names MUST return 404/403.
- Observed
- GET https://fundraisly.com/phpinfo.php -> 404 GET https://fundraisly.com/backup.sql -> 404 GET https://fundraisly.com/db.sql.gz -> 404 GET https://fundraisly.com/site.zip -> 404 GET https://fundraisly.com/backup.tar.gz -> 404
- Passing
No conventional admin/debug endpoint answered with unauthenticated internals.
- Bar met
- Conventional admin/debug surfaces (/actuator/health, /actuator/env, /debug, /server-status, /admin, /wp-admin exposed to the world) SHOULD require auth or return 403/404 unauthenticated. An open actuator/env or server-status leaking internals is a warn escalating toward fail if secrets are shown.
- Observed
- GET https://fundraisly.com/actuator -> 404 GET https://fundraisly.com/actuator/env -> 404 GET https://fundraisly.com/actuator/health -> 404 GET https://fundraisly.com/server-status -> 404 GET https://fundraisly.com/debug -> 404
- Passing
Port-80 request returns 308 to the identical HTTPS host before serving content.
- Bar met
- First hop from http:// must be a redirect to https:// on the same host. Observatory: redirection-missing = -20, redirection-not-to-https = -20, redirection-off-host-from-http = -5; redirection-to-https = 0 (clean).
- Observed
- GET http://fundraisly.com/ -> 308 location: https://fundraisly.com/
- Passing
The connection negotiated TLSv1.3; TLS 1.2 is the floor and 1.3 is preferred.
- Bar met
- TLS 1.0 and TLS 1.1 MUST NOT be used (RFC 8996); serve TLS 1.2 as the floor, TLS 1.3 preferred.
- Observed
- negotiated protocol: TLSv1.3
- Passing
The certificate is within its validity window (expires Nov 19 15:07:15 2026 GMT, ~66 days).
- Bar met
- Certificate must be trusted, hostname-matching, unexpired, and chain-complete (no missing intermediates). Observatory flags hsts-invalid-cert / redirection-invalid-cert = -20 when the chain fails.
- Observed
- issuer: Let's Encrypt notAfter: Nov 19 15:07:15 2026 GMT protocol: TLSv1.3
- Passing
No dangling CNAME to an unclaimed third-party resource was found among the apex, www and document host.
- Bar met
- No subdomain CNAME MUST point to a deprovisioned third-party resource (GitHub Pages, S3, Heroku, Fastly, Netlify) that an attacker could re-register. A dangling CNAME whose target returns a provider 'no such site' fingerprint is a fail.
- Observed
- fundraisly.com: no CNAME www.fundraisly.com: CNAME -> sites.framer.app (only the document host, apex and www are resolvable from a URL; a full subdomain enumeration is out of scope)
- Passing
DMARC reaches enforcement (p=quarantine) with an rua= reporting address.
- Bar met
- A DMARC record MUST exist and reach enforcement (p=quarantine or p=reject) with an rua= aggregate-report address. p=none is monitor-only and blocks nothing; it is a valid starting point but not a passing end state.
- Observed
- TXT _dmarc.fundraisly.com -> "v=DMARC1; p=quarantine; rua=mailto:admin@fundraisly.com"
- Passing
A DKIM public key is published at the google._domainkey selector.
- Bar met
- A mail-sending domain SHOULD publish a DKIM public key (v=DKIM1; p=…) reachable at its provider's selector, so DMARC has a second aligned authentication method beyond SPF. Absence cannot be proven passively (selectors are arbitrary), so this is advisory, not a hard fail.
- Observed
- TXT google._domainkey.fundraisly.com -> "v=DKIM1; k=rsa; p=MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAs/j/FqBpoFDVu/bPqq…"
- Measured, nothing to grade
CSP weakened by 'unsafe-inline' / 'unsafe-eval'
- Why grey
- No enforced CSP is present; unsafe-inline/eval weakening only applies once a policy exists.
- Threshold
- script-src must not contain 'unsafe-inline' or 'unsafe-eval'. Observatory: csp-implemented-with-unsafe-inline = -20, csp-implemented-with-unsafe-eval = -10; a nonce/hash-based policy with no unsafe = +5.
- Fix
- Replace 'unsafe-inline' with per-request nonces or hashes (`script-src 'self' 'nonce-<rand>'`); style-src 'unsafe-inline' alone is tolerated but still worth removing.
- Measured, nothing to grade
Session cookie missing Secure / HttpOnly / SameSite
- Why grey
- The homepage set no cookies; session cookies issued on authenticated routes are not observable from a URL alone.
- Threshold
- Session cookies must carry Secure, HttpOnly, and SameSite=Lax|Strict. Observatory: cookies-session-without-secure-flag = -40, cookies-session-without-httponly-flag = -30, cookies-anticsrf-without-samesite-flag = -20; fully hardened = +5.
- Fix
- Add Secure (HTTPS-only), HttpOnly (no JS access), and SameSite=Lax (or Strict) to every session/auth cookie.
Compliance
Consent, policy pages, and the disclosures you owe.
The score grades your consent flow and the policy pages you owe your visitors.
2 of 21 measured failing
- Failing
WCAG 1.1.1 Non-text Content (image alt text)
- Measured
- 1 of 102 images have no alt attribute
- Threshold
- WCAG 2.2 SC 1.1.1 Non-text Content (Level A): all non-text content needs a text alternative that serves the equivalent purpose; purely decorative images need alt="" (empty, but present). A scanner reliably detects MISSING alt attributes; it CANNOT judge whether present alt text is meaningful. That requires human review.
- Observed
- 1/102 non-text elements lack alt (Level A) e.g. https://i.ytimg.com/vi_webp/pkRCPWSh4mE…
- Fix
- Add descriptive alt to informative images and alt="" to decorative ones. The 5 filename-style values must be reviewed by a human. Automated tooling can flag them but not rewrite them correctly.
- Needs work
No easy, persistent way to withdraw consent
- Measured
- no persistent consent-settings control found
- Threshold
- Withdrawing consent must be as easy as giving it, and possible at any time (GDPR Art. 7(3), binding). Regulators expect a persistent, always-reachable mechanism (e.g. a footer 'Cookie settings' link or floating icon). The persistence expectation is EDPB/CNIL guidance layered on the binding withdrawal right.
- Observed
- no footer link or widget to reopen preferences and withdraw consent (note: a JS-injected floating icon would not appear in static HTML)
- Fix
- Add an always-available control (footer 'Cookie settings' link or floating icon) that reopens the preferences panel, letting users withdraw with effort no greater than the original acceptance.
- Needs work
Controller legal identity / imprint (e-Commerce Directive Art. 5)
- Measured
- no imprint / legal-identity disclosure found
- Threshold
- Art. 5(1) of Directive 2000/31/EC requires every commercial online service to render 'easily, directly and permanently accessible' at minimum: the provider's name, geographic address of establishment, email, and, where registered, trade-register and VAT identifiers. The CJEU (C-298/07) held email alone is insufficient; a second rapid, direct contact channel is required.
- Observed
- no imprint/impressum/legal/contact link, no /imprint* path, and no schema.org Organization address
- Fix
- Publish an imprint/legal-notice page with the registered entity name, establishment address, email, and a second contact channel (phone or contact form), plus register/VAT numbers where applicable. Link it permanently from the footer.
- Needs work
Accessibility statement (European Accessibility Act)
- Measured
- no accessibility statement found
- Threshold
- Directive (EU) 2019/882 (EAA) applies from 28 June 2025 to consumer-facing products/services including e-commerce, banking, e-books, and transport ticketing. In-scope services must meet the accessibility requirements and provide information on how the service meets them (an accessibility statement). Microenterprises providing services (<10 staff AND ≤€2m turnover/balance sheet) are exempt for services. The statement's presence is the signal; national transposing law governs enforcement.
- Observed
- no /accessibility route, no accessibility link, and no WCAG/EN 301 549 reference (EAA scope depends on service type and the microenterprise carve-out, which are not detectable)
- Fix
- If in scope and not a microenterprise, publish an accessibility statement describing how the service meets the EAA requirements (typically via EN 301 549 / WCAG 2.1 AA). Confirm scope and the microenterprise carve-out manually. Turnover/headcount are not detectable from the site.
- Needs work
Security / breach reporting contact disclosure
- Measured
- no security contact disclosure
- Threshold
- GDPR imposes a binding breach-notification duty on the controller (Art. 33-34) but does not require a public breach contact on the website. A published, machine-findable security contact is BEST PRACTICE per RFC 9116 (security.txt), which is an informational standard, not law. The detectable signal is a security.txt or a named security/privacy contact.
- Observed
- no /.well-known/security.txt or /security.txt and no security/vulnerability contact on the page (this is RFC 9116 guidance, not a legal violation)
- Fix
- Publish /.well-known/security.txt with a 'Contact:' field and add a privacy/DPO contact to satisfy the separate Art. 13 DPO-contact requirement. Distinguish clearly: security.txt is voluntary guidance; the Art. 13 DPO contact (where a DPO exists) is binding.
- Needs work
Data-subject-rights request route & stated response timeframe
- Measured
- no usable rights-request route
- Threshold
- Art. 12(2) requires the controller to 'facilitate the exercise' of data-subject rights, and Art. 12(3) sets a binding deadline: respond without undue delay and at the latest within one month of receipt (extendable by two further months for complex requests, with notice). A published, usable request route and, as good practice, a stated timeframe are the visible signals.
- Observed
- the policy discusses rights abstractly but exposes no privacy contact, DSAR form, or request channel
- Fix
- Provide a specific channel (privacy@ address or a form) for rights requests and state the one-month statutory response window. The one-month deadline is binding regardless of whether it is published; publishing it is the detectable signal.
- Needs work
WCAG 1.3.1 / 2.4.4 Heading order & discernible link names
- Measured
- 4 link(s) with no accessible name
- Threshold
- WCAG 2.2 SC 1.3.1 Info and Relationships (Level A) requires a programmatically correct heading hierarchy; SC 2.4.4 Link Purpose (In Context) (Level A) and SC 4.1.2 require each link to have a discernible, purposeful accessible name. Skipped heading levels and empty/duplicate link names are machine-detectable; whether headings are logically ordered in MEANING is a manual judgement.
- Observed
- outline levels: H2 H2 H2 H2 H2
- Fix
- Insert the missing <h2> levels so headings never skip; give icon links an aria-label and make repeated 'Read more' links unique or add aria-label with context. Confirm the heading ORDER makes sense to a human reader.
- Passing
a privacy policy resolves (200)
- Bar met
- Any site collecting personal data (contact forms, analytics, account signup, server logs of IP addresses) must provide the Article 13 information at the point of collection. The information must actually be published and reachable, not merely drafted. A URL is the only signal a scanner can see.
- Observed
- https://fundraisly.com/privacy-policy → 200, 8457 words
- Passing
terms document linked and reachable
- Bar met
- Unlike the privacy notice, there is no single EU statute mandating a published ToS for every site, but for any paid or contractual service the pre-contract information duties of the Consumer Rights Directive (2011/83/EU) and e-Commerce Directive Art. 10 make published terms effectively necessary. Presence of a linked, reachable terms document is the signal; adequacy is not machine-checkable.
- Observed
- 'Terms Of Service' → https://fundraisly.com/terms-of-service (200)
- Passing
all 8 machine-detectable Art. 13 topics present
- Bar met
- Art. 13(1)-(2) enumerates a closed list that must ALL appear: controller identity + contact, DPO contact (where applicable), purposes AND legal basis, legitimate interests (if that basis is used), recipients/categories, transfer information, retention period, the data-subject rights, right to withdraw consent, right to complain to a supervisory authority, and whether provision is a statutory/contractual requirement.
- Observed
- policy references: controller identity/contact, purposes of processing, legal basis, recipients/categories, retention period, data-subject rights, right to withdraw consent, right to lodge a complaint
- Passing
transfer mechanism disclosed (4 US recipient(s))
- Bar met
- Art. 13(1)(f) requires stating that a transfer to a third country occurs and 'the existence or absence of an adequacy decision' or the appropriate safeguards (Chapter V). Post-Schrems II, US transfers rely on the recipient's EU-US Data Privacy Framework self-certification OR on SCCs plus a transfer impact assessment. The scanner can only detect that a US recipient exists and that no transfer basis is disclosed.
- Observed
- US-operated hosts present (fonts.gstatic.com, googletagmanager.com, i.ytimg.com) and the policy names a transfer basis
- Passing
children's data is addressed
- Bar met
- Art. 8 GDPR: where an information-society service is offered directly to a child on the basis of consent, processing is lawful only for a child of at least 16 (Member States may lower this to 13), and below that age parental consent is required. This check only applies where the service targets or foreseeably reaches minors and relies on consent: it is conditional, not universal.
- Observed
- the policy addresses children's data / a minimum age / parental consent
- Passing
page language declared: lang="en"
- Bar met
- WCAG 2.2 Success Criterion 3.1.1 Language of Page (Level A): the default human language of each page must be programmatically determinable via a valid lang attribute on <html>. This is fully machine-detectable and one of the highest-confidence automated checks.
- Observed
- <html lang="en"> is a valid BCP 47 tag
- Passing
all 18 inline colour pairs meet 4.5:1
- Bar met
- WCAG 2.2 SC 1.4.3 Contrast (Minimum) (Level AA): normal text must reach a 4.5:1 contrast ratio against its background; large text (≥18pt, or ≥14pt bold) must reach 3:1. Contrast is computable from colour values, but overlaps, gradients, images-behind-text, and opacity can defeat static analysis. Those cases need manual verification.
- Observed
- every element with an inline colour + background pair reaches AA (external/class-based colours not evaluated)
- Measured, nothing to grade
No 'Reject all' control on the banner's first layer
- Why grey
- This can't be determined from a URL alone.
- Threshold
- If 'Accept all' is present on a given layer, a same-layer 'Reject all' should be present. The EDPB Cookie Banner Taskforce records this as the majority DPA position; it is a supervisory-authority interpretation, not settled across all authorities, so it is a strong recommendation rather than uniform binding law.
- Fix
- Add a 'Reject all' button on the first layer, functionally equivalent to and no more effortful than 'Accept all'. One click to refuse should mirror one click to accept.
- Measured, nothing to grade
Tracking cookies mislabelled as 'strictly necessary'
- Why grey
- This can't be determined from a URL alone.
- Threshold
- The strictly-necessary exemption to consent (Art. 5(3)) covers only storage 'strictly necessary' to provide a service explicitly requested by the user. Analytics and advertising identifiers do not qualify and cannot be classified as essential. Binding law; the EDPB Taskforce lists 'essential' misclassification as a common infringement.
- Fix
- Reclassify analytics and advertising cookies into consent-gated Analytics/Marketing categories. Reserve 'strictly necessary' for session, security, load-balancing, and explicit user-requested functionality.
- Measured, nothing to grade
Banner omits cookie duration and third-party recipients
- Why grey
- This can't be determined from a URL alone.
- Threshold
- Users must be told, before consenting, the duration of the operation of cookies and whether third parties may have access to them (CJEU Planet49, binding). Absence of this information undermines informed consent.
- Fix
- Disclose, at the point of consent, each cookie's retention duration and the third parties (or vendor categories) that can access the stored information, e.g. via an accessible cookie table or vendor list.
- Measured, nothing to grade
Consent / re-prompt lifetime exceeds 13 months
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- Consent should be refreshed at a reasonable interval; CNIL recommends the consent record not exceed 13 months and identifiers no more than ~13 months. This is a French supervisory-authority recommendation (jurisdiction-specific), not an EU-wide statutory maximum. Treat as a warn, not a hard fail.
- Fix
- Cap the consent-record lifetime at 13 months and re-prompt on expiry. Applies where French/CNIL exposure is relevant; elsewhere confirm the local authority's interval.
- Measured, nothing to grade
Missing 'Do Not Sell or Share My Personal Information' link
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- A business that sells or shares personal information must provide a clear and conspicuous opt-out link, titled 'Do Not Sell or Share My Personal Information' or offer the 'Your Privacy Choices' control (CCPA/CPRA). Binding within California; applicability depends on the business meeting CCPA thresholds and on it 'selling/sharing', jurisdiction- and status-scoped.
- Fix
- If CCPA applies and cross-context advertising is used, add a conspicuous 'Do Not Sell or Share My Personal Information' (or 'Your Privacy Choices') link that opts the user out, and honour it alongside GPC.
- Measured, nothing to grade
WCAG 3.3.2 / 4.1.2 Form field labels
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- WCAG 2.2 SC 3.3.2 Labels or Instructions (Level A) and SC 4.1.2 Name, Role, Value (Level A): every form control must have a programmatically associated, persistent label. Placeholder text is not a label (it vanishes on input). Missing programmatic labels are machine-detectable; whether an existing label is clear is not.
- Fix
- Associate a visible <label for> with each control (or aria-label where a visible label is impossible). Do not rely on placeholder text as the label.
Does it work
Links, forms and flows that fail silently.
The score grades the links and forms we could open and submit.
21 checks, none failing
- Passing
0 of 6 sampled internal links return 4xx
- Bar met
- Zero linked 4xx URLs. Google removes previously-indexed URLs that return any 4xx (except 429) from the index and treats the content as non-existent, so every internal link to a 4xx wastes crawl and leaks link equity.
- Observed
- all reachable — sampled 6 of 6 internal links (cap 15)
- Passing
0 of 6 checked URLs return 5xx
- Bar met
- Zero 5xx on crawlable URLs. Googlebot slows crawling on 5xx and, if the errors persist, drops the affected URLs from the index; crawl rate only recovers once the server returns 2xx again.
- Observed
- no server error in sample — checked 6 URL(s), cap 15
- Passing
no redirect loop in 7 sampled chains
- Bar met
- Zero loops. A URL that eventually redirects back to itself never resolves; Googlebot abandons it after 10 hops and the page becomes uncrawlable and unindexable.
- Observed
- every chain terminated within 10 hops — followed 7 internal link(s), 10-hop budget, cap 15
- Passing
no active http:// subresources
- Bar met
- Zero active (blockable) mixed content. On an HTTPS page, browsers hard-block active http:// resources (scripts, stylesheets, iframes, XHR/fetch) because they can rewrite the whole page. Blocked scripts/CSS break functionality outright.
- Observed
- all scripts/stylesheets/iframes are https or protocol-relative
- Passing
4 critical subresources all load (200, CORS ok)
- Bar met
- Every referenced script, stylesheet, and font must return 200 with correct CORS. A 4xx on a stylesheet or a CORS-blocked font degrades or breaks the rendered page, and Google may classify the resulting broken render as a soft 404.
- Observed
- no 4xx/CORS failure in sample — probed 4 of 4 subresources (cap 15); 1 answered from a second network after our first request was refused
- Passing
3 assets served with correct MIME types
- Bar met
- Scripts must be served with a JavaScript MIME type and stylesheets with text/css. With X-Content-Type-Options: nosniff (increasingly default behaviour), a script sent as text/plain or a CSS file sent as text/html is blocked outright.
- Observed
- scripts are JS, stylesheets text/css — probed 3 of 4 script/CSS assets (cap 15)
- Passing
longest chain 0 hop(s)
- Bar met
- Keep redirects to a single hop. Google's crawlers follow up to 10 redirect hops and then give up, treating the URL as an error; every extra hop also adds latency and dilutes the signal. Anything over 3 hops is a warning, over 10 a hard failure.
- Observed
- every sampled URL resolves in ≤2 hops — followed 7 internal link(s) (cap 15)
- Passing
directives agree with the served response
- Bar met
- Directives must agree with reality. A canonical pointing at a non-200 URL, a self-referencing canonical on a page that 301s elsewhere, or 'index' + 'noindex' both present are self-contradictions Google resolves unpredictably. ~0.7% of pages in the 2025 Web Almanac show a canonical mismatch.
- Observed
- canonical resolves to a live 200; robots directives consistent
- Passing
no combinatorial parameter pattern in homepage links
- Bar met
- URL parameters must not multiply into a near-infinite crawl space. Faceted navigation, sort/filter params, session IDs, and calendar 'next month' links generate effectively unbounded duplicate URLs that exhaust crawl budget on low-value pages.
- Observed
- 0 of 7 homepage links carry query strings; distinct params: none. Full-space detection needs a crawl.
- Passing
15 sampled sitemap URLs all return 200
- Bar met
- Sitemap URLs should return 200, be canonical, not noindex, and not be robots-blocked. A single sitemap file is capped at 50,000 URLs and 50MB uncompressed. Past that, Google ignores the overflow or rejects the file.
- Observed
- within size limits; sampled 15 <loc> URL(s) (cap 15)
- Passing
7 of 7 internal request(s) responded without error
- Bar met
- Keep server response time low and consistent; web.dev rates TTFB good at <=800ms, poor above 1,800ms. Network timeouts and connection resets are treated by Googlebot like 5xx server errors and quickly suppress the URL in Search.
- Observed
- sampled 7 same-origin request(s); wall-clock median 164ms (includes our client queue — an upper bound, not a pure TTFB)
- Passing
HTTP/3 advertised via Alt-Svc
- Bar met
- Serve at least HTTP/2, which multiplexes requests over one connection and removes head-of-line blocking. In the 2024 Web Almanac ~70-71% of sites use HTTP/2; HTTP/3 is a bonus (leading CDNs reach ~69% adoption vs <5% of origins).
- Observed
- Alt-Svc: h3=":443"; ma=2592000
- Measured, nothing to grade
Form cannot submit: no action, no handler, no endpoint
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- Every form must have a working submission path: a resolvable action endpoint or a bound submit handler, and a control whose type actually submits. A form that silently discards input is a dead conversion surface.
- Fix
- Add a valid action + method or a bound onSubmit that POSTs to a real endpoint and calls preventDefault; make the trigger <button type="submit"> (that is the default, but broken wrappers override it). Confirm the handler is attached post-hydration.
- Measured, nothing to grade
Form endpoint errors on valid, well-formed input
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- A non-transactional form given valid input must reach a success state, not a server error. Unexpected post-submit failures are a top driver of form/checkout abandonment.
- Fix
- Fix the endpoint's 500 (validate/log server-side), return a 2xx with a confirmation the UI can render, and show an explicit error message on failure instead of silently resetting. NEVER exercise this on transactional/account-creating forms.
- Measured, nothing to grade
Site search or filter returns nothing / errors on valid queries
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- Search and filter controls must return correct, non-empty results for queries that should match, without console errors. A broken search/filter silently strands users on discovery paths.
- Fix
- Fix the search endpoint's 500 and ensure filter changes actually trigger a re-fetch/re-render (bind the change handler post-hydration). Verify a known-match query returns the expected items.
- Measured, nothing to grade
Valid input rejected, and no inline validation before submit
- Why grey
- We read this one and there was nothing on your site to grade.
- Threshold
- Well-formed input must be accepted, and forms should validate inline (on blur) so errors surface before submission. 31% of sites lack inline validation; unexpected post-submit errors are a documented abandonment driver.
- Fix
- Replace the broken regex with permissive email validation (or rely on type="email" + server check), and add on-blur inline validation that clears once corrected, so users are not stopped by a surprise error at submit.
Speed & visual
How fast it loads and how it renders at every size.
The score is Google's performance number for your mobile page, plus how your layout holds at every screen size.
2 of 17 measured failing · 5 grey
PageSpeed · Lighthouse categories & Core Web Vitals
Mobile · ranked
Load sequence
Desktop
Load sequence
- Failing · mobile, ranked
Unused JavaScript shipped to the client
- Measured
- Est savings of 4,223 KiB
- Threshold
- The lab audit flags scripts with large unused byte counts (default > ~2 KB wasted per resource, aggregated). Target: ship only what the route needs.
- Observed
- Lighthouse mobile 'Reduce unused JavaScript': 26 flagged, ~19650 ms est. savings, ~4.1 MB est. savings.
- Fix
- Code-split by route, dynamic-import below-the-fold and interaction-only components, tree-shake dead exports, and lazy-load third-party SDKs after load. Verify with the DevTools Coverage tab.
DesktopEst savings of 3,504 KiBLab audit: Reduce unused JavaScript - Failing · mobile, ranked
Main-thread work during load
- Measured
- Main-thread work = 7.3 s (Lighthouse mobile)
- Threshold
- The lab audit warns as main-thread time climbs (guideline: keep total under ~2 s and individual tasks under 50 ms). Long tasks (> 50 ms) block input.
- Observed
- Lighthouse mobile Main-thread work: 7.3 s (7303 ms).
- Fix
- Reduce JS execution (see speed-unused-js), memoize expensive renders, offload heavy pure computation to a Web Worker, and yield long tasks. Every millisecond cut here helps both TBT and INP.
DesktopMain-thread work = 4.1 s (Lighthouse desktop)Lab audit: Minimize main-thread work - Needs work · mobile, ranked
Field-data availability (field vs lab coverage)
- Measured
- No CrUX field data (mobile) — Core Web Vitals here are lab (Lighthouse) estimates only
- Threshold
- Field data only reports a URL/origin once it has sufficient real-user samples over the 28-day window. Low-traffic pages fall back to origin-level data or have none at all.
- Observed
- mobile: page-level absent, origin-level absent. New or low-traffic site — every field metric falls back to a lab estimate.
- Fix
- Treat field data as the source of truth for pass/fail and the lab audit as the diagnostic for why. Where no field data exists, label results 'lab estimate' and instrument a RUM/web-vitals beacon to build first-party field data.
DesktopNo CrUX field data (desktop) — Core Web Vitals here are lab (Lighthouse) estimates onlyField data (real-user) - Needs work · mobile, ranked
Lab performance score (weighted)
- Measured
- Performance = 51 / 100 (Lighthouse mobile)
- Threshold
- 0 to 49 poor (red) · 50 to 89 needs improvement (orange) · 90 to 100 good (green). Weighted average: TBT 30% · LCP 25% · CLS 25% · FCP 10% · Speed Index 10%.
- Observed
- Lighthouse mobile performance 51/100 under simulated throttling. Lab score — the CrUX field verdict governs Core Web Vitals pass/fail.
- Fix
- Prioritize by weight: TBT and LCP together are 55% of the score, so shipping the hydration-bundle and LCP-image fixes above moves the number most. CLS is already green and contributes little upside.
DesktopPerformance = 61 / 100 (Lighthouse desktop)Lab audit: Performance scoring - Measured, nothing to grade
Largest Contentful Paint (field, p75)
- Why grey
- No field data yet: not enough real-user traffic to report page-speed history.
- Threshold
- Good ≤ 2.5 s · Needs improvement 2.5 to 4.0 s · Poor > 4.0 s, evaluated at the 75th percentile of real-user page loads
- Fix
- Preload the LCP image with fetchpriority="high", drop it from any lazy-loading, and serve a correctly-sized AVIF/WebP. Cut the render-blocking chain ahead of it so the browser discovers the image sooner.
- Measured, nothing to grade
First Contentful Paint (field, p75)
- Why grey
- No field data yet: not enough real-user traffic to report page-speed history.
- Threshold
- Good ≤ 1.8 s · Needs improvement 1.8 to 3.0 s · Poor > 3.0 s at p75. Field and lab metric; not a Core Web Vital.
- Fix
- The same two fixes move FCP: cut TTFB (caching/CDN) and clear render-blocking CSS/JS. FCP improvement usually pulls LCP down with it since they share the early critical path.
- Measured, nothing to grade
Cumulative Layout Shift (field, p75)
- Why grey
- No field data yet: not enough real-user traffic to report page-speed history.
- Threshold
- Good ≤ 0.10 · Needs improvement 0.10 to 0.25 · Poor > 0.25 at p75. CLS is unitless (a layout-shift score, not a time).
- Fix
- Already within budget. Hold the line by setting width/height (or aspect-ratio) on all media, reserving space for embeds/ads, and using font-display: optional or size-adjust to neutralize the font swap.
- Measured, nothing to grade
Interaction to Next Paint (field, p75)
- Why grey
- No field data yet: not enough real-user traffic to report page-speed history.
- Threshold
- Good ≤ 200 ms · Needs improvement 200 to 500 ms · Poor > 500 ms at p75. INP replaced FID as a Core Web Vital in March 2024.
- Fix
- Break up the long input handler (yield with scheduler.yield or setTimeout), defer non-critical work off the interaction path, and shrink hydration cost. Use the TBT lab proxy (speed-tbt-lab) to catch regressions between field readings.
- Measured, nothing to grade
Time to First Byte (field, p75)
- Why grey
- No field data yet: not enough real-user traffic to report page-speed history.
- Threshold
- Good ≤ 0.8 s · Needs improvement 0.8 to 1.8 s · Poor > 1.8 s at p75. TTFB is a diagnostic (not itself a Core Web Vital) and available as both field and lab.
- Fix
- Add full-page or edge caching / CDN in front of the origin, cache expensive DB queries, and stream the HTML (early flush) so bytes leave the server before the full page is assembled.
- Not measured
LCP sub-part budget (load delay dominating)
- Why grey
- The service this check relies on did not answer on this read. Your next scan asks again at no extra charge.
- Fix
- Eliminate the load-delay gap: put the LCP image in the initial HTML (not injected by JS), add <link rel="preload" fetchpriority="high">, and clear render-blocking resources ahead of it. Optimizing only download size will shift time between sub-parts, not reduce total LCP.
- Not measured
LCP image is lazy-loaded
- Why grey
- The service this check relies on did not answer on this read. Your next scan asks again at no extra charge.
- Threshold
- The LCP image must be eagerly loaded and, ideally, high-priority. Never apply loading="lazy" to the LCP/above-the-fold image.
- Fix
- Remove loading="lazy" from the LCP image and add fetchpriority="high". Keep lazy loading for genuinely below-the-fold images only.
- Not measured
Image weight and modern formats (AVIF/WebP)
- Why grey
- The service this check relies on did not answer on this read. Your next scan asks again at no extra charge.
- Threshold
- The lab audit flags legacy JPEG/PNG that would be meaningfully smaller as AVIF or WebP. Target: AVIF/WebP with correctly-sized, compressed variants.
- Fix
- Convert to AVIF with WebP fallback via <picture>, generate responsive srcset widths, and strip metadata. Route images through an image CDN / the framework image component so format and size are negotiated per request.
- Not measured
Text compression and static-asset caching
- Why grey
- The service this check relies on did not answer on this read. Your next scan asks again at no extra charge.
- Fix
- Enable Brotli (fallback Gzip) at the CDN/server for all text MIME types, and set Cache-Control: public, max-age=31536000, immutable on content-hashed static assets while keeping HTML short-lived.
- Not measured
Third-party script impact
- Why grey
- The service this check relies on did not answer on this read. Your next scan asks again at no extra charge.
- Fix
- Load third parties with async/defer after the main content, lazy-init the chat widget on interaction, use a facade for embeds, and add preconnect/dns-prefetch for the ones that must load early. Drop anything not earning its cost.
Unlock the full audit
What to do next.
The report above is yours, free and complete. The full audit opens the deeper checks; the rest are the things worth doing once you have read it.
Nothing on this page changes your readiness score. Every site is measured against the same bar, paid or not.
The deeper checks, each with its evidence and its fix: how AI answer engines read you, who links to you, and how the page really renders.
Featured
$19-199/wkTake the homepage hero or the top of your category for a week. A labelled badge, trending priority, and a spot in the newsletter.
Watch
$29/moKeep the audit running on a schedule and get an alert the moment a check slips: security headers, speed, broken forms, a lost backlink.
Review article
$59A full review of your product, written by us and published as its own page, based on your scan. It ranks for a name-plus-review search, gets quoted by AI answer engines, and links back to your site.
SEO / GEO / backlink boost
From $299Done-for-you off-page work: guest placements, structured-data fixes, and answer-engine optimisation so you show up in Google and in the AI answers that quote their sources.
The listing
Own this site?
Claim it, then pick a launch day.
Auditing
fundraisly.com
Send me this report
One email with what we found on fundraisly.com, and one note three days later if nobody has claimed it. Nothing after that.
Newsletter
What launched, every Monday
Every Monday: what launched on LaunchScaler that week, what is launching next, and the reviews we published. Confirm your email once and you're in.